MAX’S NOTES
Why neural networks fail on new data: overfitting
A neural network can perform well on training data and worse on examples it did not see during training. This is called overfitting: instead of learning useful general features, a model may memorize the training examples.
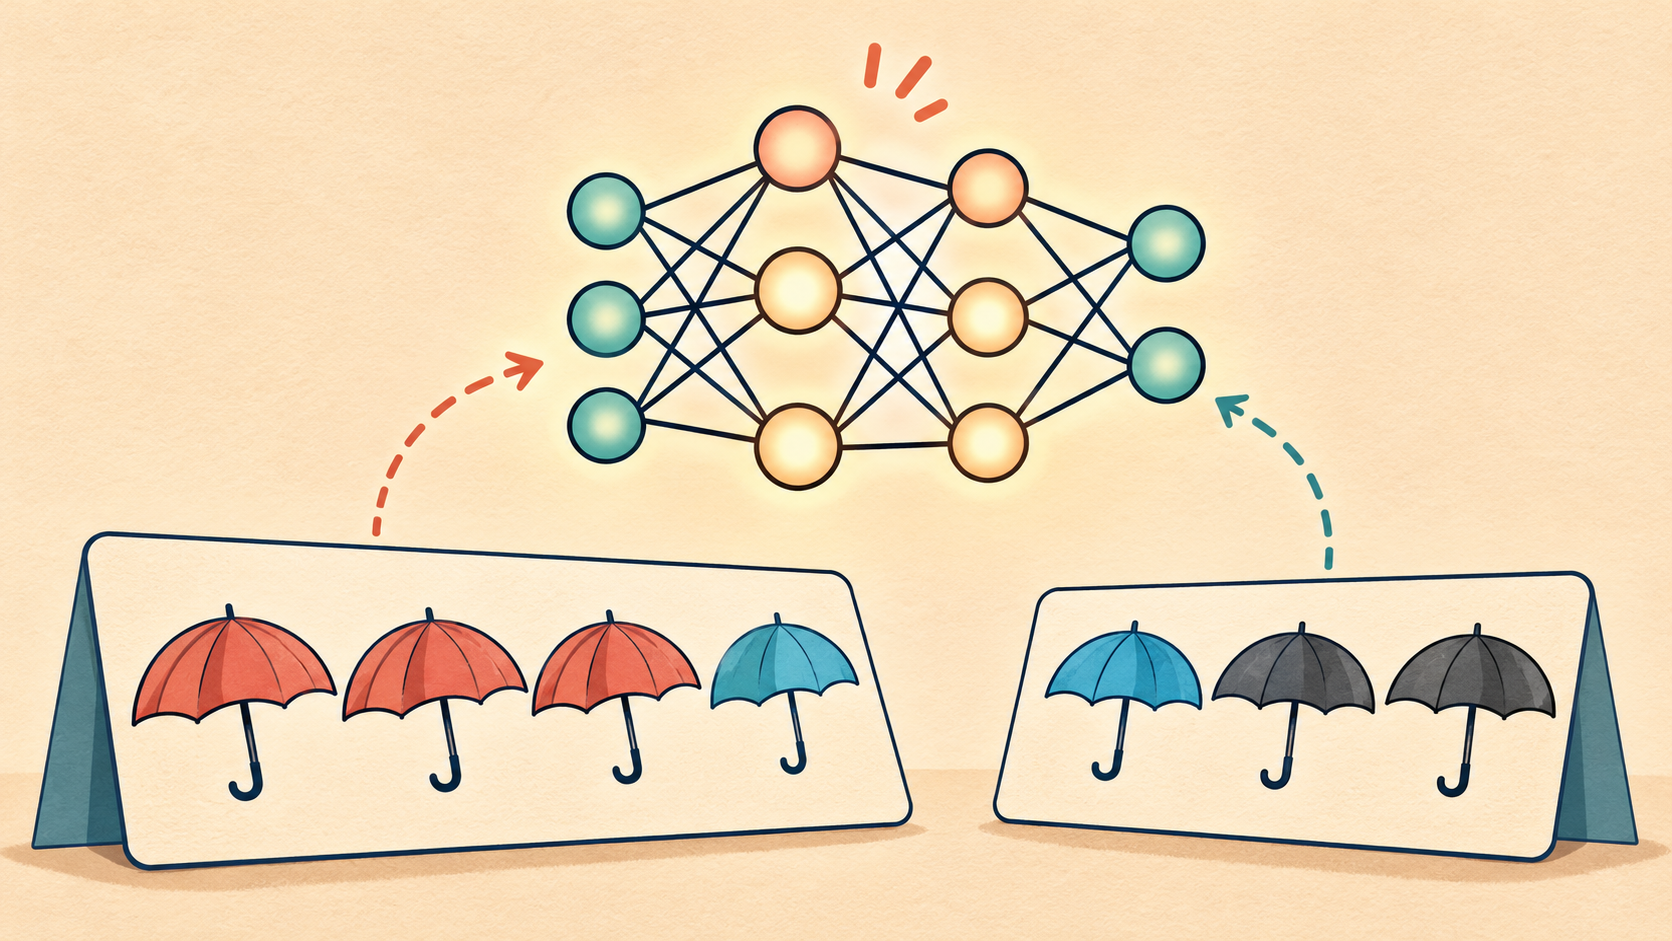
A neural network does not receive a ready-made list of rules. For tasks with labeled examples, the model adjusts its internal parameters during training to perform the task better. But a good score on familiar data does not guarantee that the model will work on new examples.
How training works
Imagine showing a program photos of umbrellas and asking it to distinguish them from walking canes. The neural network receives labeled examples and adjusts its parameters to separate the classes more accurately. This is a simplified analogy: real models work with numbers and many parameters.
What overfitting means
Overfitting is when a model performs well on training data but worse on examples it did not see during training. It is as if the model memorized a cheat sheet instead of learning the subject. The goal is to find patterns that are useful on unfamiliar examples too.
Evaluation examples should resemble the situations where the model is expected to be used. If conditions differ, performance on new data may change for several reasons; the gap between training and new examples alone does not fully explain it.
Why validation and test data matter
Data is split by role. The model learns from training examples. A validation set helps compare options during tuning. A separate test set is used for the final evaluation.
If you look at the test result repeatedly and change the model each time, the model gradually adapts to that set too. Then the test no longer provides as independent a check as it did before.
Sources
- Learn the Basics — PyTorch Tutorials
- Cross-validation: evaluating estimator performance — scikit-learn User Guide
- Debugging the training pipeline — Hugging Face LLM Course